Have you ever wondered how databases can find a single record among millions in a fraction of a second? Or how your programming language's dictionary or map implementation seems to magically pull up values almost instantly?
When an application grinds to a halt scanning a massive array with O(n) linear lookups, the most effective algorithmic fix is almost always the humble yet powerful Hash Table. Let's break down how hash tables work internally, why collisions happen, and how load factors keep them running at O(1) peak performance.
The Magic of Hashing
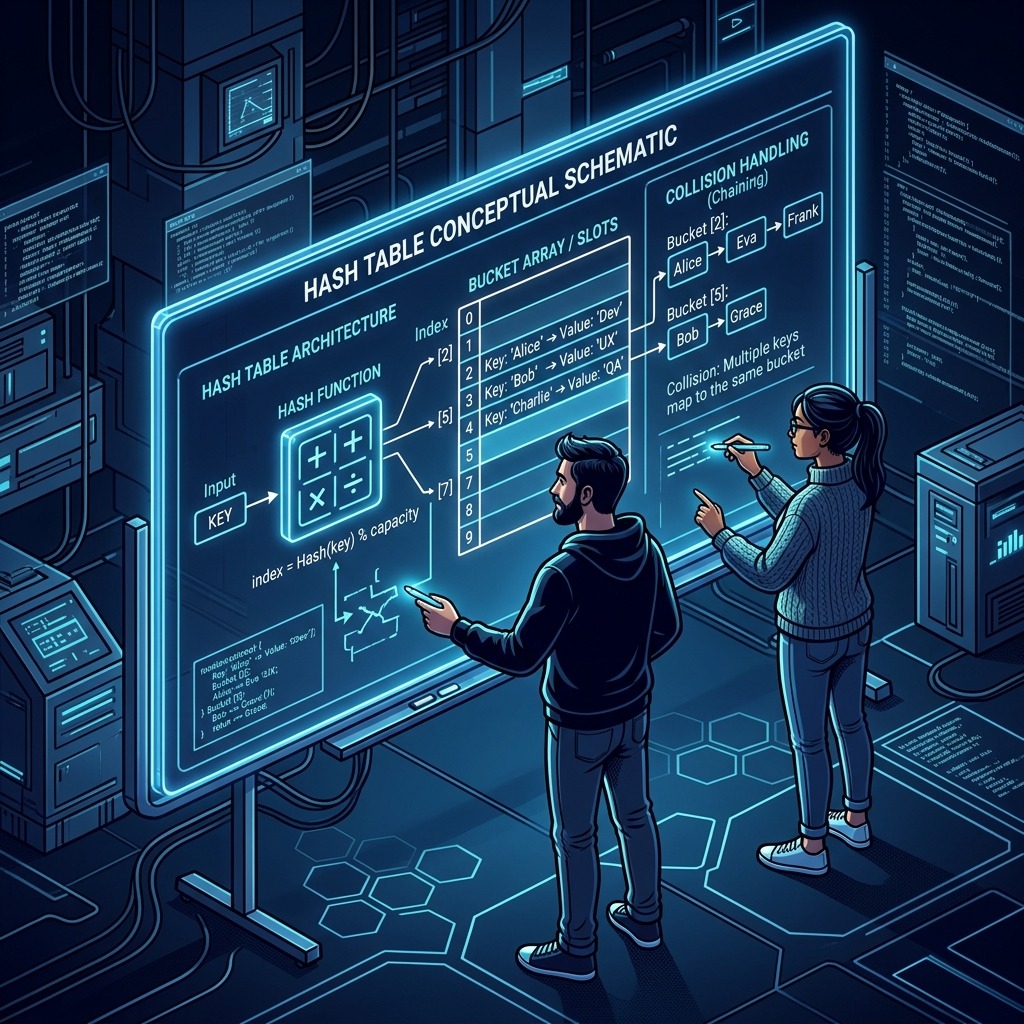
At its core, a hash table is simply an array combined with a "hash function."
Imagine you're running a massive library, but instead of organizing books by author or genre, you have a magic machine. You feed the machine a book's title (the Key), and it instantly spits out a shelf number (the Index) where that book belongs. When someone wants that book later, you don't need to search the whole library. You just feed the title into the machine again, go straight to that shelf, and grab the book (the Value).
That magic machine is your hash function. It takes an input, scrambles it predictably, and maps it to a specific index in an array (often called a bucket array). When working perfectly, this gives us O(1) constant time complexity for insertions, deletions, and lookups.
When Magic Fails: The Collision Problem
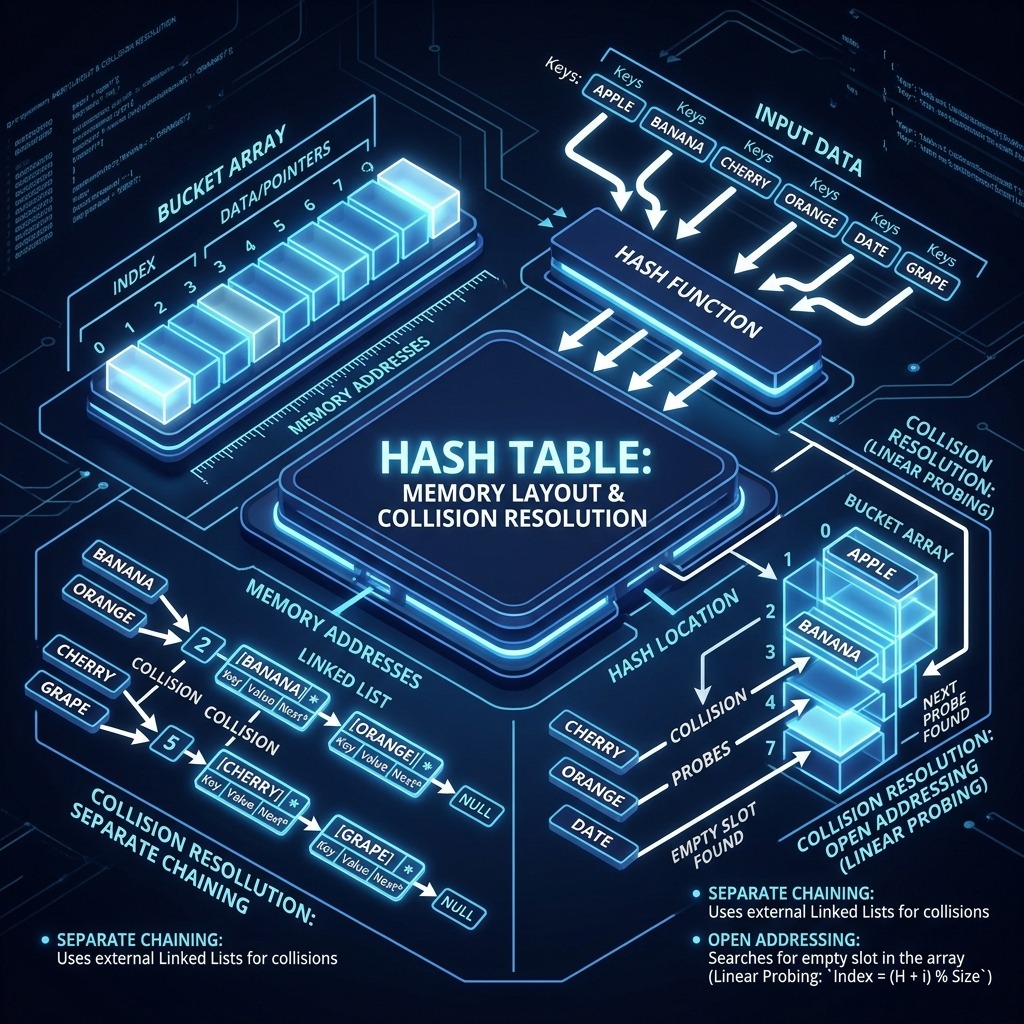
In a perfect world, our magic machine would never give two different books the same shelf number. But in the real world of computer science, arrays have limited space. Eventually, your hash function is going to take two entirely different keys and map them to the exact same index.
This is what we call a Collision.
Let's say the keys "Apple" and "Banana" both hash to index 4. We can't just overwrite "Apple" with "Banana"! We need a collision resolution strategy. The two most common approaches are:
- Separate Chaining: Instead of storing the value directly in the bucket, each bucket holds a linked list (or another data structure like a binary search tree). If "Banana" maps to index
4and "Apple" is already there, we just add "Banana" to the end of the list at index4. - Open Addressing: If index
4is taken, we look for the next available empty slot in the array. We might check index5, then6, and so on (Linear Probing), until we find an empty space.
The Balancing Act: Load Factors
You might be thinking, "If we just make the array massive, we won't have collisions!" And you'd be right, but you'd also be wasting a ridiculous amount of memory.
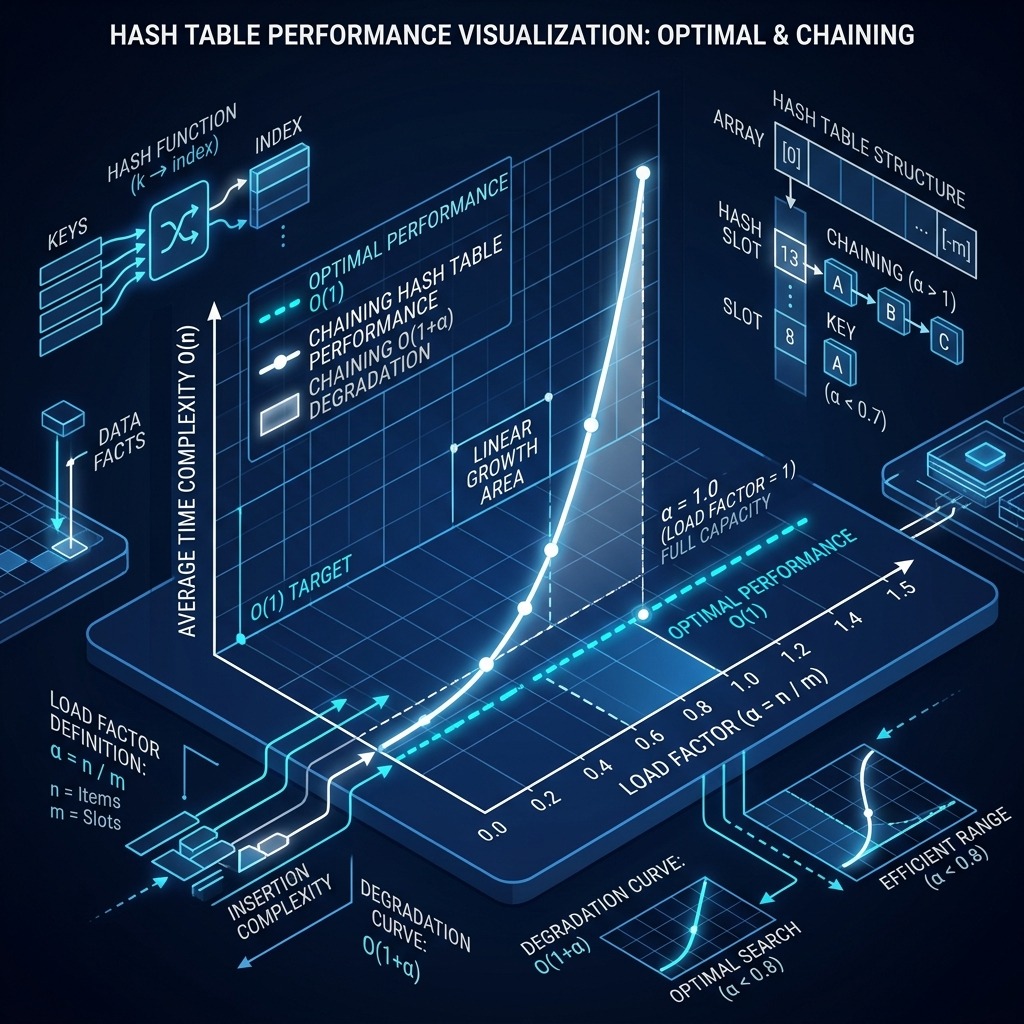
This brings us to the Load Factor, which is simply the number of entries in the hash table divided by the number of buckets (n / k).
If your load factor is too low, you're wasting memory on empty buckets. If it's too high, your buckets are getting crowded. In separate chaining, high load factors mean long linked lists. Your beautiful O(1) lookup time slowly degrades into O(n) as your program is forced to iterate through the list to find the right key.
Keeping Performance Peaked
So, how do modern languages maintain that sweet O(1) performance? They cheat by dynamically resizing.
Languages like Java or Python monitor the load factor. When it hits a certain threshold (often around 0.75, meaning the table is 75% full), the hash table automatically allocates a new, much larger underlying array (usually double the size) and rehashes all existing elements into the new array.
This rehashing operation is expensive—it takes O(n) time. But because it happens infrequently, the amortized time complexity remains O(1).
Open Addressing vs. Separate Chaining & How Load Factor Impacts Performance
When senior interviewers ask about hash tables (and queries like hash table load factor appear in system design and coding screens), they want to know how collisions, CPU cache locality, and resizing work under the hood in Python dict, Java HashMap, and Go map:
| Collision Strategy | How It Works Internally | CPU Cache Locality | Load Factor Threshold (α = N / M) | Real-World Language Implementation |
|---|---|---|---|---|
| Separate Chaining | Each bucket points to a linked list (or balanced tree) of colliding entries. | Lower (pointer chasing across heap allocations). | α = 0.75 (Java converts bucket chains of length ≥ 8 into Red-Black Trees). | Java HashMap, C++ std::unordered_map |
| Open Addressing (Linear / Quadratic Probing) | All entries live directly in a contiguous array; collisions probe subsequent slots. | Very High (contiguous memory lines in L1/L2 cache). | α = 0.66 (Python compact dict stores 1-byte/2-byte index table + dense entry array). | Python dict, Rust HashMap (SwissTable / SIMD) |
| Consistent Hashing | Maps both servers and keys onto a 2^32 unit ring with virtual nodes. | N/A (Distributed routing). | Rebalances only O(K / N) keys when a cache node joins or leaves. | Amazon DynamoDB, Apache Cassandra, Redis Cluster |
Security & Edge-Case Follow-Up: Hash DoS Attacks & Tombstone Deletions
If all keys hash to the exact same bucket, a hash table degrades from O(1) average lookup to O(n) per operation (meaning inserting n items takes O(n^2) CPU time!).
- How attackers exploit this: Sending an HTTP JSON payload with 50,000 crafted keys that collide under a deterministic hash function locks up a web server thread.
- How modern runtimes defend against it: Python, Go, and Rust randomize the hash seed (SipHash) per process startup so external callers cannot predict collisions, while Java 8+ upgrades long collision chains to
O(log n)Red-Black trees. - Why Open Addressing Requires Tombstones on Delete: In open-addressed tables, deleting a key cannot simply set the slot to
EMPTY, because doing so would prematurely terminate the probe chain for keys inserted later! Instead, deletions write aTOMBSTONEmarker that probing skips over during lookups but reuses during future insertions.
Conclusion
Hash tables are the unsung heroes of modern computing. They trade a little bit of memory and some clever math for blazing-fast performance. By understanding how collisions and load factors work under the hood, you can write more efficient code and ace those complex system design questions.
Whether you're prepping for your next technical interview on totop.app or optimizing a critical backend service, mastering the nuances of hash tables is an absolute must for any serious software engineer. Happy coding!
Practice Staff Backend Engineer Questions Live with AI Mock Interviews
Turn any job description across Engineering, DevOps, Data, Marketing, Sales, Finance, or HR into a personalized test and live voice or text AI mock interview on totop.app, or test your speed right now in the 60-Second Staff Backend Engineer Blitz.
Play 60s Staff Backend Engineer Blitz (Free, No Login) | Start 14-Day Free Trial | Browse All Interview Guides